Gümüşhane University is a public university in Turkey's Black Sea region, founded in 2008. Its Scientific Research Projects Office runs the study «The Impact of Digital Transformation on Financial Performance: Text-Mining Analysis on the BIST Sustainability Index» (BAP No: 26.B0311.02.01). The work covers annual reports, sustainability reports, integrated reports, financial audit reports and KAP disclosures for the 25 firms on the BIST Sustainability Index at year-end 2024.
ACADEMIC DATA ANALYTICS · PUBLIC TENDER · STATE UNIVERSITY
Gümüşhane Üniversitesi
Under a research project supported by the Gümüşhane University Scientific Research Projects Office and led by Assoc. Prof. Fahrettin Pala, corporate reports of 25 firms on the BIST Sustainability Index are analysed using text-mining methods. AIOR Teknoloji Limited Şirketi carried out the data collection, processing and delivery processes for this project under a public tender. Within this scope, a ten-year corporate document archive for 2015–2024 was compiled systematically; annual reports, sustainability reports, integrated reports, independent audit reports and Public Disclosure Platform (KAP) disclosures were processed through OCR and natural language processing (NLP). As a result, the university research team received 910 unique PDF documents, a fully verified 1,250-cell source matrix, a 35.8-million-word text corpus, digitalisation scores, a panel dataset comprising 19 variables, and an offline delivery portal that documents the full workflow step by step.
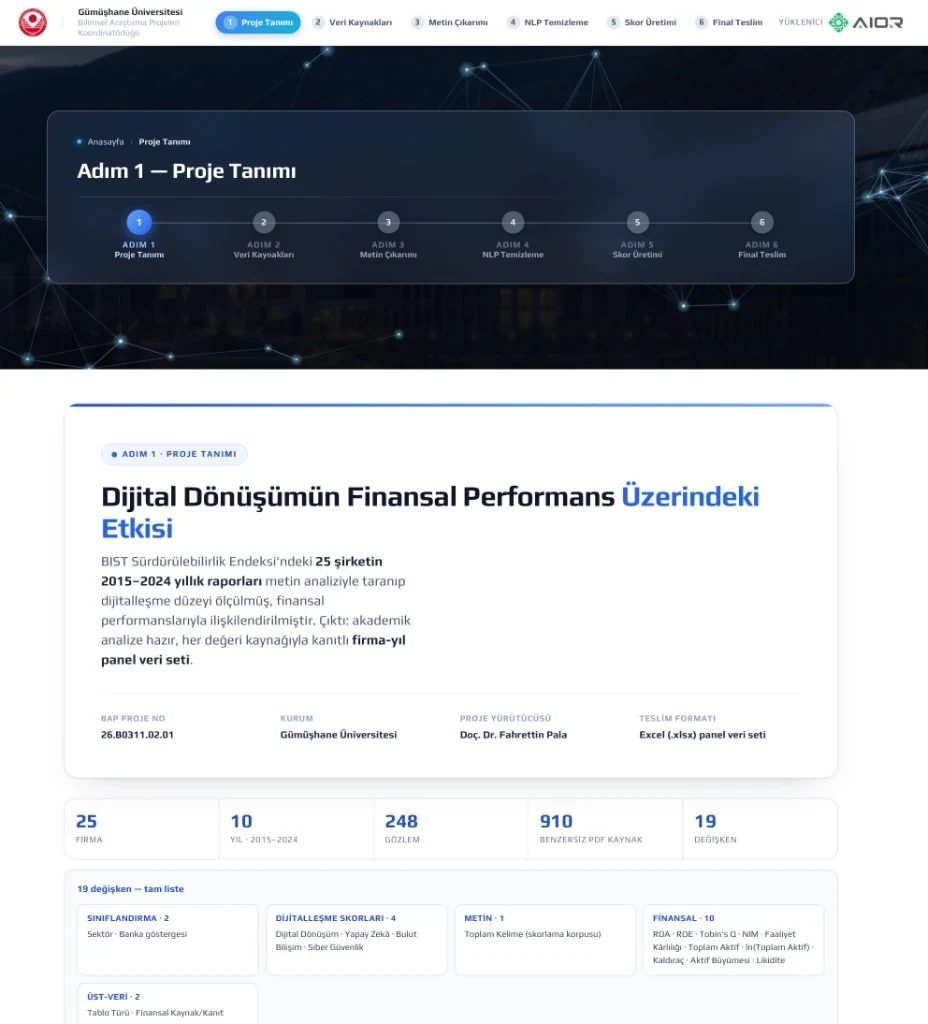
PROJECT GALLERY
Screens from the delivered digital experience
PROJECT STORY
Project overview and scope
Under a research project supported by the Gümüşhane University Scientific Research Projects Office and led by Assoc. Prof. Fahrettin Pala, corporate reports of 25 firms on the BIST Sustainability Index are analysed using text-mining methods. AIOR Teknoloji Limited Şirketi carried out the data collection, processing and delivery processes for this project under a public tender. Within this scope, a ten-year corporate document archive for 2015–2024 was compiled systematically; annual reports, sustainability reports, integrated reports, independent audit reports and Public Disclosure Platform (KAP) disclosures were processed through OCR and natural language processing (NLP). As a result, the university research team received 910 unique PDF documents, a fully verified 1,250-cell source matrix, a 35.8-million-word text corpus, digitalisation scores, a panel dataset comprising 19 variables, and an offline delivery portal that documents the full workflow step by step.
The scope was to build the full data infrastructure the study required, end to end. AIOR collected raw data for 25 firms, five document types and a ten-year period; created a structured PDF archive and a firm-year-category matrix. PyMuPDF and Tesseract were used together for text extraction; Turkish and English texts were cleaned and tokenised. A digitalisation lexicon and TF-IDF scores were produced. The panel dataset was delivered in Excel with a variable dictionary (codebook). The package also included a 23-page offline HTML portal, methodology report, statistical summary, random evidence audit and academic-use licence. All files were bundled in a Teslim.zip archive of approximately 5.3 GB.
In an academic delivery, the critical expectation is clear traceability for every data point. Across the 1,250-cell matrix, each firm-year-category intersection had to be verified with a unique PDF, SHA256 hash, local file path and live URL together. Gaps in KAP download links, OCR noise in scan-quality PDFs, disaggregation of integrated reports and consistent extraction of ROA, ROE, Tobin's Q and NIM from financial tables required sustained engineering work. Under public tender rules, delivery date, technical specification compliance and data integrity had to be met at the same time.
AIOR built a six-stage data pipeline. First came the unique source catalogue, then the structured archive and matrix mapping. PDFs with a text layer were read directly; scan-quality files went through Tesseract OCR. A spaCy-based NLP pipeline cleaned Turkish and English texts. Digitalisation lexicon and TF-IDF scores were produced, and the panel dataset was assembled. A comparison view was added for each cell, showing source PDF, raw text and NLP output side by side. Throughout delivery, HTML reports, CSV records and archive files were kept synchronised to show identical figures.
DELIVERABLES
Modules completed within the project
- 01Project management aligned with the public tender, technical specification tracking and delivery schedule
- 02Collection of 910 unique PDFs, each mapped to a SHA256 hash, local path and live source URL
- 031,250-cell firm-year-category matrix (annual, sustainability, integrated, financial, KAP)
- 04PDF text extraction: 439 text-layer + 471 hybrid OCR extractions; ~35.8 million words in total
- 05Turkish and English NLP cleaning, tokenisation and scoring corpus
- 06Digitalisation lexicon sub-scores: digital transformation, AI, cloud, cyber security
- 07Panel dataset with 248 observations and 19 variables, plus variable dictionary
- 08Offline delivery portal, document comparison views, methodology report and Teslim.zip archive
- 09Random evidence audit, statistical summary and academic-use licence
TECHNOLOGY STACK
Platforms and tools used
PythonspaCyscikit-learnPyMuPDFTesseract OCRPlaywrightpandasopenpyxlTF-IDFSHA256 Evidence ChainOffline HTML PortalPublic Tender DeliveryBAP Academic Dataset
1.250
Verified matrix cells
910
Unique sources (PDF + OCR)
248
Firm-year observations
19
Panel variables
AIOR PROJECT NOTE
In this project, every figure has a document behind it, and every document has a source behind it. The Gümüşhane delivery is a fully auditable data infrastructure that lets researchers follow the full path from raw PDF to analysis output in a single package.
Delivered scope and continuity
Delivery was completed on 8 June 2026. The university research team received the panel dataset, variable dictionary, CSV source files, statistical summary, document comparison views and six-step offline portal in full. All 910 unique PDFs, 910 OCR text files and 1,250 matrix cells were verified. Researchers can trace every step from the raw document to the NLP output; the dataset is ready for academic reproducibility.